August 19, 2024
Data Virtualisation Explained Simply
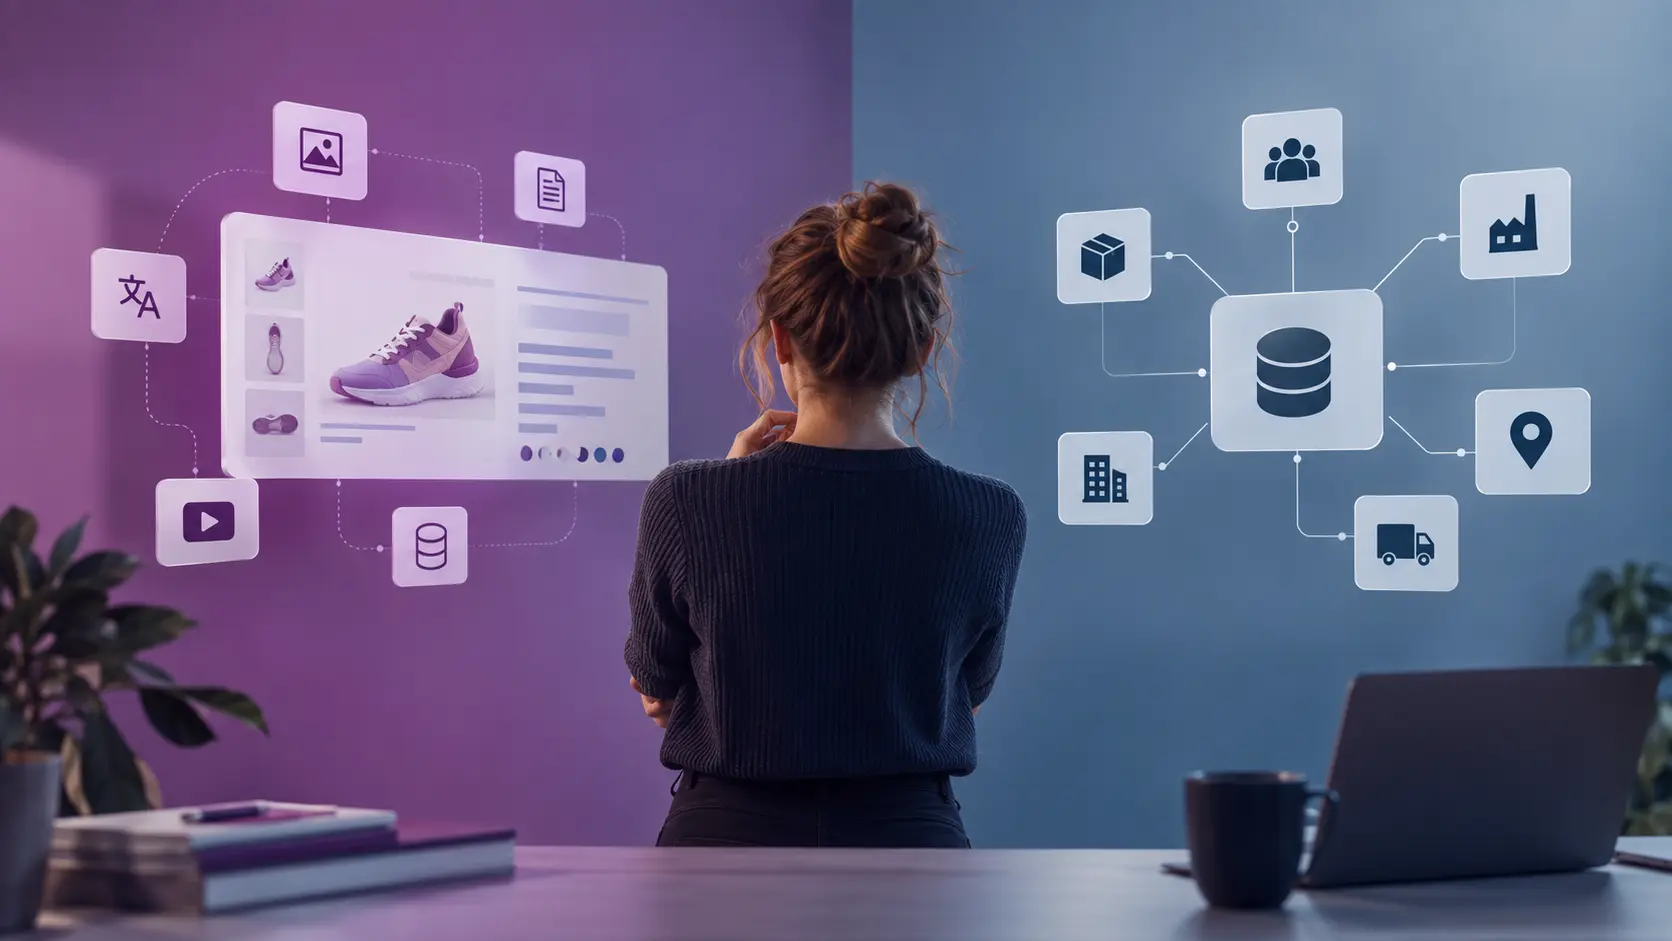
Many companies are aware of the value of their data. The greater challenge is actually making that value usable. Today, business data is distributed across ERP, CRM, PIM, MDM and other operational systems, data warehouses and data lakes, as well as cloud platforms and external data sources. To use this data collectively for analytics, operational processes or AI applications, companies need consistent and straightforward access.
Many companies are aware of the value of their data. The greater challenge is actually making that value usable. Today, business data is distributed across ERP, CRM, PIM, MDM and other operational systems, data warehouses and data lakes, as well as cloud platforms and external data sources. To use this data collectively for analytics, operational processes or AI applications, companies need consistent and straightforward access.
This requirement is not new. For decades, data from different sources has been integrated and made centrally available to users. However, hybrid cloud environments, growing data volumes, real-time requirements and AI have significantly changed the requirements for data integration.
Data virtualisation offers a logical approach: instead of first physically consolidating data in a new location for each use case, it creates a virtual access layer across different data sources. In this blog article, we explain what data virtualisation is, how it differs from traditional data integration and what role it plays in modern data architectures such as data fabric and data mesh.
What is data virtualisation?
Data virtualisation is a technology for logical data integration. It enables data from different sources to be made available through a common access layer without necessarily having to be physically stored in a central system. The data generally remains in its source systems. The virtualisation layer abstracts their technical differences and provides users, applications or analytics tools with a unified view of the required data.
This allows data from ERP, CRM, PIM, data warehouses, data lakes or cloud applications, for example, to be queried together even though it physically remains in different systems. Data virtualisation does not completely replace traditional data integration. Rather, it complements ETL/ELT, APIs, streaming and other integration methods by providing logical access to distributed data.
Physical and virtual data integration: What is the difference?
Data integration refers to the process of connecting data from different sources so that it can be used collectively. A fundamental distinction can be made between physical and virtual or logical data integration.
With physical data integration, data is actually moved or replicated between systems. In the traditional ETL process – Extract, Transform, Load – data is extracted from different source systems, transformed and subsequently loaded into a target system such as a data warehouse. Modern architectures also use approaches such as ELT, change data capture or streaming to transfer data between systems more efficiently or in near real time.
The advantage of physical integration is that data can be specifically prepared for particular analytics and processing purposes and made available with high performance in a target system. At the same time, additional data copies, pipelines and transformation processes are created that need to be operated and kept up to date.
With virtual data integration, by contrast, the data generally remains in its respective source systems. A logical abstraction layer connects the sources and provides the required data in a unified view when a query is made. This reduces the need to replicate data for every new use case. At the same time, data consumers are decoupled from the technical complexity of the underlying systems.
Physical data integration
- Principle: Data is moved or replicated
- Typical technologies: ETL, ELT, CDC, streaming
- Storage: Additional physical data storage
- Data currency: Dependent on pipelines and synchronisation
- Performance: Can be optimised for defined workloads
- Flexibility: Changes may require adjustments to pipelines
- Suitable for: Persistent analytics data, historical analyses, high workloads
Virtual data integration
- Principle: Data is logically combined
- Typical technologies: Data virtualisation, federation
- Storage: Data generally remains in the source systems
- Data currency: Current source data can be queried
- Performance: Dependent on sources, network and query optimisation
- Flexibility: New sources and views can often be integrated more quickly
- Suitable for: Distributed data, rapid provisioning, operational and current data views
In practice, the decision is rarely ETL or data virtualisation. Modern data architectures combine physical and logical integration methods depending on the respective use case.
How does data virtualisation work?
A logical data layer is created between data sources and data consumers. This layer connects to the different source systems and abstracts their technical structures.
When a user or application submits a request, the virtualisation layer translates it into corresponding queries to the source systems involved. The results are then combined and provided in the required format. This gives the data consumer a unified view even though the underlying information continues to originate from multiple physical sources.
Modern data virtualisation platforms can also centrally manage semantic models, metadata, access rights, security policies and governance rules. As a result, the logical data layer becomes not only a technical integration layer, but also a way to provide data consistently and in a controlled manner.
What role does data virtualisation play in data fabric and data mesh?
Data virtualisation is frequently mentioned in connection with data fabric and data mesh. However, the three terms describe different things:
Data fabric
A data fabric is an architectural approach designed to simplify access to data across different systems, clouds and organisational areas. It combines different technologies and methods – including metadata management, data integration, data governance, automation and data virtualisation. Data virtualisation can therefore be an important component of a data fabric, but it is not the same thing.
A logical access layer can make data from different systems available without first having to replicate it centrally for every use case. Other data, by contrast, continues to be provided via ETL/ELT, streaming or other integration methods.
Data mesh
Data mesh, by contrast, primarily describes an organisational and architectural principle. Data responsibility is distributed more extensively across individual business domains. Business units take ownership of specific data and make it available to other areas as so-called data products. Instead of concentrating all responsibility within a central data team, the aim is for data to be managed by the areas that understand its business context best.
Data virtualisation can technically support a data mesh by facilitating cross-domain access to distributed data. However, it is not a prerequisite for a data mesh. APIs, data platforms and other integration mechanisms can also provide data products.
Data fabric and data mesh are not mutually exclusive either. A data fabric can, for example, provide technical capabilities that make the data products managed in a decentralised manner within a data mesh discoverable, accessible and usable under common governance rules.
What are the benefits of data virtualisation?
Particularly in heterogeneous and hybrid data environments, data virtualisation can offer significant benefits for both business and IT.
- Faster data access. Data does not first have to be copied to an additional data platform and prepared there for every new use case. New integrated data views can therefore often be made available more quickly.
- Less unnecessary data replication. As data can generally remain in its source systems, additional copies and the associated storage and administration effort can be reduced.
- Greater agility. The logical abstraction layer further decouples data consumers from physical data sources. Changes to the system landscape can therefore be accommodated more easily – provided that the logical data models and interfaces are maintained accordingly.
- More up-to-date data views. Data virtualisation can access current source data directly. This makes it particularly suitable for use cases that require current information from multiple operational systems.
- Unified data access and governance. A central logical data layer can help implement access rights, security rules and semantic definitions more consistently across different data sources.
- Better foundation for analytics and AI. Analytics and AI applications require access to relevant and contextualised enterprise data. Data virtualisation can help make distributed data accessible to these applications more quickly without first having to build a new physical data pipeline for every use case.
What are the limitations of data virtualisation?
Data virtualisation is not a replacement for every form of data integration. When very large volumes of data are repeatedly processed for complex analytical workloads, physical materialisation in a data warehouse or lakehouse may be more efficient. The performance of source systems, network latency and complex queries can also affect the speed of virtual data access.
At the same time, a virtualisation layer does not solve fundamental data quality problems. If product, customer or supplier data in the source systems is incorrect, redundant or inconsistent, these issues are not automatically resolved through virtual access.
Data virtualisation must therefore be part of a broader data strategy that combines data integration, data governance, data quality, metadata management and – where required – master data management.
Data virtualisation as a building block for AI readiness
With the increasing use of generative and agentic AI, this question is becoming even more important. Enterprise AI does not necessarily require all data to be held in a single central repository. What matters instead is that relevant data is available reliably, up to date, contextualised and subject to clear access rules.
A logical data layer can, for example, provide AI applications or agents with controlled access to information from different enterprise systems. Instead of creating new data copies and individual integrations for every AI use case, existing data sources can be made available through defined data services.
Conclusion: The right data integration depends on the use case
Data virtualisation creates a logical access layer for distributed enterprise data and can therefore significantly reduce the complexity of modern data environments. Its greatest advantage is not that it completely replaces traditional data integration, but that it provides an additional way to make data usable flexibly and, wherever possible, without unnecessary replication.
In modern data architectures, the aim is to find the right combination of ETL/ELT, APIs, streaming, data virtualisation and other integration methods for each use case in order to optimise response times, performance, flexibility and data storage.
This is exactly where the experience of our experts comes into play: they do not consider data architecture in isolation from the systems and business processes that generate and use data. From integration and data governance to MDM and data quality, through to analytics and AI enablement, they develop data architectures that make data available where it actually creates business value.
Frequently asked questions about data virtualisation
What is data virtualisation?
Data virtualisation is a method of logical data integration. A virtual access layer connects different data sources and provides their data in a unified view without requiring all data to first be physically copied into a central system.
What is the difference between ETL and data virtualisation?
With ETL, data is extracted from source systems, transformed and loaded into a target system. With data virtualisation, it generally remains in its source systems and is queried and combined through a logical layer. Both approaches can be used within the same data architecture.
Is data copied during data virtualisation?
In principle, data virtualisation enables access to data without prior physical replication. However, modern platforms can additionally use caching, materialisation or other integration methods when this makes sense for performance reasons, for example.
What is the difference between data fabric and data virtualisation?
A data fabric is a comprehensive architectural approach for providing and managing data across an organisation. Data virtualisation is a technology that can be used within a data fabric to make distributed data available through a common logical layer.
What role does data virtualisation play in AI?
Data virtualisation can provide AI applications with unified and controlled access to current data from different enterprise systems. It can therefore serve as a building block of an AI-ready data architecture, but it does not replace data quality, governance or semantic preparation.
Strategic Advisory & Effective Execution
We continuously innovate to transform data into competitive advantage via expert advisory, effective project execution, and precision engineering.

Our Blog for Experts.
We use our expertise in various disciplines to turn data into sustainable competitive advantages for our customers and to share our knowledge.

Further News
All the latest news about Advellence